
Fitting an ERGM and Viewing the Output with tabulergm
Source:vignettes/ergm-with-tabulergm.Rmd
ergm-with-tabulergm.RmdOverview
This vignette demonstrates how to:
- Fit an ERGM using the ergm package.
- Produce a publication-ready Markdown table with
tabulergm_table(format = "markdown"). - Render the table inline in a Quarto or R Markdown document using
results: asis. - Replace the shipped term titles, descriptions, and citations for a single table.
- Interactively preview the table in the RStudio viewer (or a browser)
with
tabulergm_view().
Fitting the model
We use the Florentine marriage network, which ships with
ergm, and fit a simple model with an edges
term and a nodematch term for wealth quartile.
data(florentine)

model <- ergm(
  flomarriage ~ edges + nodematch("wealth"),
  control = control.ergm(seed = 42)
)
summary(model)
#> Call:
#> ergm(formula = flomarriage ~ edges + nodematch("wealth"), control = control.ergm(seed = 42))
#>
#> Maximum Likelihood Results:
#>
#>                  Estimate Std. Error MCMC % z value Pr(>|z|)
#> edges             -1.5892     0.2454      0  -6.477   <1e-04 ***
#> nodematch.wealth     -Inf     0.0000      0    -Inf   <1e-04 ***
#> ---
#> Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
#>
#>      Null Deviance: 166.4  on 120  degrees of freedom
#>  Residual Deviance: 107.4  on 118  degrees of freedom
#>
#> AIC: 109.4  BIC: 112.2  (Smaller is better. MC Std. Err. = 0)
#> Warnings:
#>
#>  * The following terms have infinite coefficient estimates due to an
#>    extreme sufficient statistic:
#>
#>    nodematch.wealth
Creating a Markdown table
Calling tabulergm_table() with
format = "markdown" returns a knitr_kable
object. Adding the chunk option results: asis (or
results = "asis" in R Markdown) causes knitr to emit the
table verbatim, so the Markdown renderer (Quarto, Pandoc, GitHub, etc.)
formats it properly.
Math notation in the math column is automatically
wrapped in $...$ so that Pandoc can render it reliably in
table cells across output formats, including Word. Network figures in
the figure column are emitted with Markdown image
syntax.
Quarto tip: use
#| results: asis(orresults = "asis"in R Markdown) on the chunk so that knitr emits the table verbatim instead of quoting it.
tabulergm_table(
  model,
  include_math        = TRUE,
  include_description = TRUE,
  format              = "markdown"
)| term | figure | estimate | se | pvalue | description | math |
|---|---|---|---|---|---|---|
| edges | 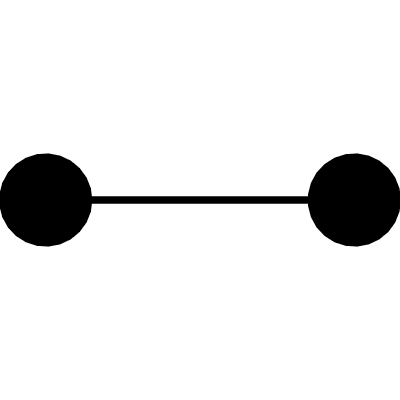 |
-1.59 | 0.25 | <0.01 | Counts the ties present in the network. Acts as the baseline density term, playing the role an intercept plays in a regression model. (holland1981) | |
| nodematch | 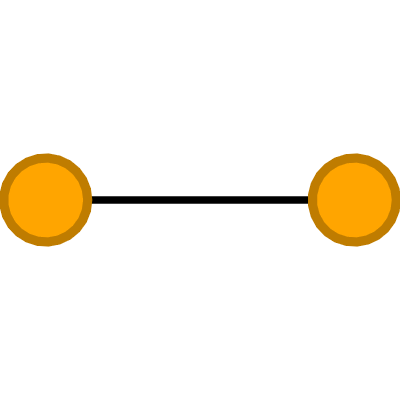 |
-Inf | 0.00 | <0.01 | Counts the ties joining nodes that share the same value of a categorical attribute, the standard measure of homophily. Setting diff = TRUE adds one statistic per attribute value (differential homophily). (wasserman1996; mcpherson2001) |
Note: Orange nodes indicate nodes with a focal attribute.
doi:10.1080/01621459.1981.10477598
doi:10.1007/BF02294547
doi:10.1146/annurev.soc.27.1.415
Customizing titles, descriptions, and citations
Each term carries a short title and a plain-language
description, taken from tabulergm’s term
dictionary and falling back to the ergm term database for
terms the dictionary does not cover. Add the title column
with include_title = TRUE, and replace either field for a
single table with the override.* arguments:
tabulergm_table(
  model,
  include_title       = TRUE,
  include_description = TRUE,
  override.title      = c(edges = "Density"),
  override.desc       = c(edges = "Baseline propensity to form ties."),
  format              = "markdown"
)| term | title | figure | estimate | se | pvalue | description |
|---|---|---|---|---|---|---|
| edges | Density | |
-1.59 | 0.25 | <0.01 | Baseline propensity to form ties. (holland1981) |
| nodematch | Uniform homophily | |
-Inf | 0.00 | <0.01 | Counts the ties joining nodes that share the same value of a categorical attribute, the standard measure of homophily. Setting diff = TRUE adds one statistic per attribute value (differential homophily). (wasserman1996; mcpherson2001) |
Note: Orange nodes indicate nodes with a focal attribute.
doi:10.1080/01621459.1981.10477598
doi:10.1007/BF02294547
doi:10.1146/annurev.soc.27.1.415
override.math, override.figure, and
override.citation work the same way, and the single
override argument sets several fields at once:
tabulergm_table(
  model,
  override = list(
    edges     = list(title = "Density", desc = "Baseline tie propensity."),
    nodematch = list(citation = "doi:10.1016/S0378-8733(01)00029-6")
  )
)
Override names are matched against the term name first and the
coefficient name second, so an expanded coefficient such as
nodematch.wealth.3 can be targeted on its own.
Terms with a citation show a (key) marker next to their
description, and the matching [key] identifier line is
appended below the table. Citations are stored as a DOI, arXiv id,
PubMed id, or URL rather than a formatted reference, so readers can
import them into their own bibliography software:
tabulergm_table(
  flomarriage ~ gwesp(0.5, fixed = TRUE) + gwdegree(0.5, fixed = TRUE),
  format = "markdown"
)| term | figure | math | description |
|---|---|---|---|
| gwesp | 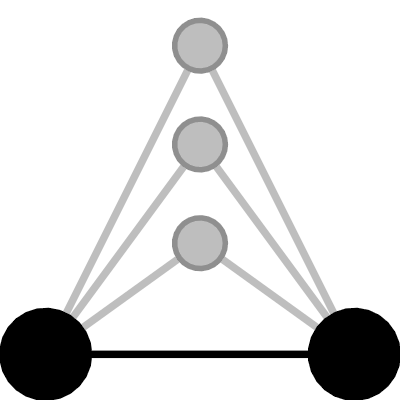 |
Summarizes how many partners tied nodes share, weighting each additional shared partner geometrically less than the last. Provides a better-behaved measure of transitive closure than a raw triangle count; the decay parameter controls how fast the weights fall off. (snijders2006; hunter2007) | |
| gwdegree | 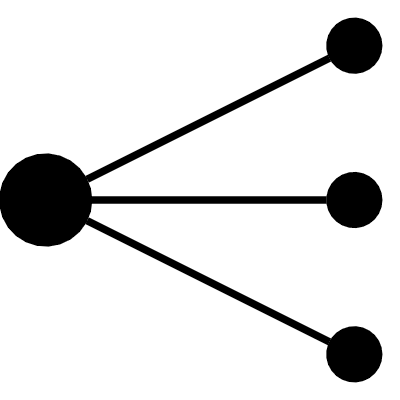 |
Summarizes the degree distribution with geometrically decreasing weights. Captures whether ties concentrate on a few high-degree nodes or spread evenly, and stabilizes models that would otherwise degenerate. (snijders2006; hunter2007) |
doi:10.1111/j.1467-9531.2006.00176.x
doi:10.1016/j.socnet.2006.08.005
Reorganizing a table with styles
The default table uses one column per metadata component. For a
compact dictionary-style layout, pipe a table through
with_style_name_over_formula(). It places the curated title
over the formula in a Name cell and puts the term
drawing in Representation, while retaining model
statistics and any columns explicitly requested from
tabulergm_table().
tabulergm_table(
  flomarriage ~ edges + nodematch("wealth") + triangle,
  include_description = FALSE,
  format = "markdown"
) |>
with_style_name_over_formula()| Name | Representation |
|---|---|
|
Number of edges (holland1981) |
|
|
Uniform homophily (wasserman1996; mcpherson2001) |
|
|
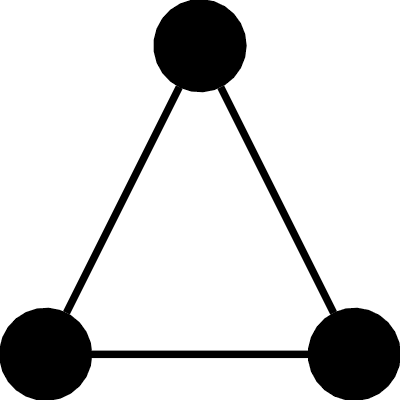
Triangles (frank1986) |
|
Note: Orange nodes indicate nodes with a focal attribute.
[holland1981]
doi:10.1080/01621459.1981.10477598
[wasserman1996]
doi:10.1007/BF02294547
[mcpherson2001]
doi:10.1146/annurev.soc.27.1.415
[frank1986]
doi:10.1080/01621459.1986.10478342
Styled Markdown is emitted as a raw HTML table because pipe tables
cannot reliably hold the multi-line name/formula cells. This layout is
therefore for HTML-capable Markdown targets; use the default plain style
for portable pipe tables. with_style_plain() restores the
original layout.
The same styled data frame can be saved or previewed through a pipe:
tabulergm_table(model, include_description = FALSE) |>
  with_style_name_over_formula() |>
  tabulergm_save("compact-ergm")

tabulergm_table(model, include_description = FALSE) |>
  with_style_name_over_formula() |>
  tabulergm_view()
The compact LaTeX snippet requires the array,
booktabs, and graphicx packages for multiline
cells and figures. Fitted-model estimates, standard errors, and p-values
display two decimal places by default; use digits = NULL to
retain full precision or set another number of decimal places.
Compact-style presentation settings are carried by the table object,
so the same layout is used for previews and saved output.
column_widths takes named fractions of the table width and
figure_height is measured in inches:
tabulergm_table(model, include_description = FALSE) |>
  with_style_name_over_formula(
    column_widths = c(Name = .5, Representation = .2),
    figure_height = .8
  ) |>
  tabulergm_save("compact-ergm")
Inspecting a formula without a fitted model
You can also pass a bare formula to inspect term metadata before fitting:
tabulergm_table(
  flomarriage ~ edges + nodematch("wealth") + triangle,
  format = "markdown"
)| term | figure | math | description |
|---|---|---|---|
| edges | |
Counts the ties present in the network. Acts as the baseline density term, playing the role an intercept plays in a regression model. (holland1981) | |
| nodematch | |
Counts the ties joining nodes that share the same value of a categorical attribute, the standard measure of homophily. Setting diff = TRUE adds one statistic per attribute value (differential homophily). (wasserman1996; mcpherson2001) | |
| triangle | |
Counts the sets of three mutually connected nodes, the basic measure of local clustering in an undirected network. (frank1986) |
Note: Orange nodes indicate nodes with a focal attribute.
doi:10.1080/01621459.1981.10477598
doi:10.1007/BF02294547
doi:10.1146/annurev.soc.27.1.415
doi:10.1080/01621459.1986.10478342
The term dictionary
tabulergm ships math and network drawings for commonly
used ERGM terms, including directed variants and mode-specific bipartite
terms (b1* terms summarize the first mode, and
b2* terms summarize the second mode). The table below
covers every term currently included in the dictionary; terms with both
directed and undirected definitions (edges,
gwesp, gwdsp, isolates) display
the undirected version:
dictionary_terms <- network ~
  edges + mutual + triangle +
  gwesp(0.5, fixed = TRUE) + gwdsp(0.5, fixed = TRUE) +
  gwdegree(0.5, fixed = TRUE) + altkstar(2, fixed = TRUE) +
  nodematch("attr") + nodefactor("attr") + nodemix("attr") +
  nodecov("attr") + absdiff("attr") + edgecov("cov") +
  transitiveties + cyclicalties +
  nodeicov("attr") + nodeocov("attr") +
  gwidegree(0.5, fixed = TRUE) + gwodegree(0.5, fixed = TRUE) +
  nodeifactor("attr") + nodeofactor("attr") +
  kstar(2) + istar(2) + ostar(2) +
  isolates + degree(1) + concurrent +
  dgwesp(0.5, fixed = TRUE) + dgwdsp(0.5, fixed = TRUE) +
  gwb1dsp(0.5, fixed = TRUE) + gwb2dsp(0.5, fixed = TRUE) +
  gwb1degree(0.5, fixed = TRUE) + gwb2degree(0.5, fixed = TRUE) +
  b1factor("type") + b2factor("group") +
  b1nodematch("type") + b2nodematch("group") +
  b1starmix(2, "type") + b2starmix(2, "group")

tabulergm_table(dictionary_terms, format = "markdown")| term | figure | math | description |
|---|---|---|---|
| edges | |
Counts the ties present in the network. Acts as the baseline density term, playing the role an intercept plays in a regression model. (holland1981) | |
| mutual | 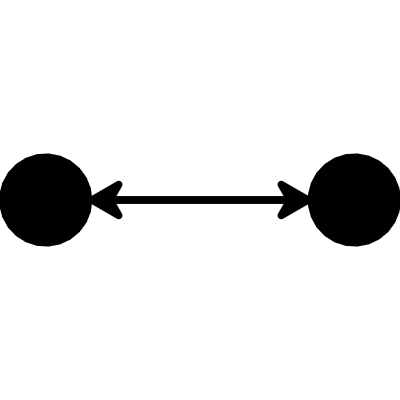 |
Counts the dyads in which both directed ties are present, capturing the tendency for ties to be returned. (holland1981) | |
| triangle | |
Counts the sets of three mutually connected nodes, the basic measure of local clustering in an undirected network. (frank1986) | |
| gwesp | |
Summarizes how many partners tied nodes share, weighting each additional shared partner geometrically less than the last. Provides a better-behaved measure of transitive closure than a raw triangle count; the decay parameter controls how fast the weights fall off. (snijders2006; hunter2007) | |
| gwdsp | 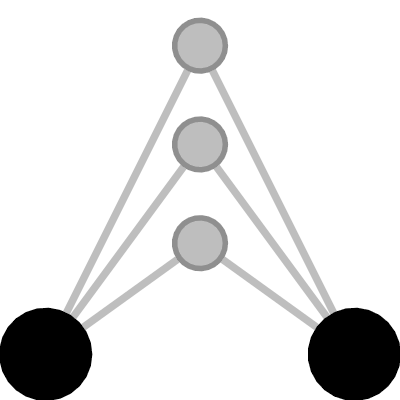 |
Summarizes shared partners over every dyad, tied or not, with geometrically decreasing weights. Commonly paired with gwesp to separate shared partnership from closure itself. (snijders2006; hunter2007) | |
| gwdegree | |
Summarizes the degree distribution with geometrically decreasing weights. Captures whether ties concentrate on a few high-degree nodes or spread evenly, and stabilizes models that would otherwise degenerate. (snijders2006; hunter2007) | |
| altkstar | 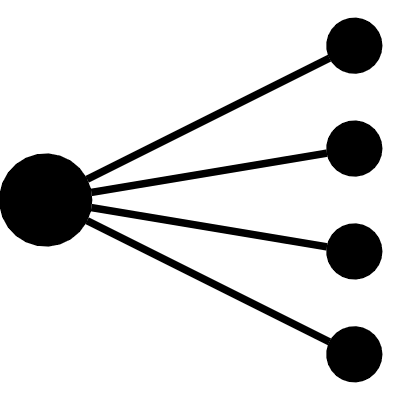 |
Alternating sum of the k-star counts, an equivalent parameterization of the geometrically weighted degree distribution used to model degree heterogeneity. (snijders2006; hunter2007) | |
| nodematch | |
Counts the ties joining nodes that share the same value of a categorical attribute, the standard measure of homophily. Setting diff = TRUE adds one statistic per attribute value (differential homophily). (wasserman1996; mcpherson2001) | |
| nodefactor | 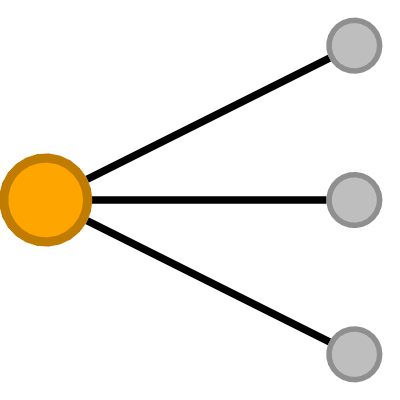 |
Counts the tie endpoints belonging to each level of a categorical attribute, measuring how active nodes with that value are in forming ties. | |
| nodemix | 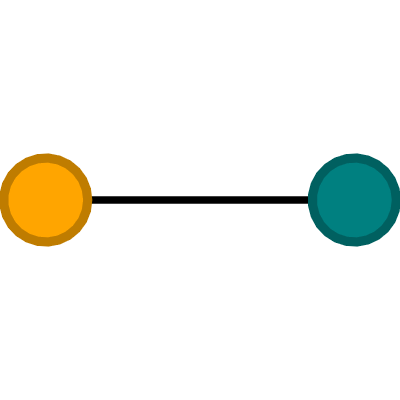 |
Counts the ties for every pairing of attribute values, reproducing the full mixing matrix of a categorical attribute. (wasserman1996; morris1991) | |
| nodecov | 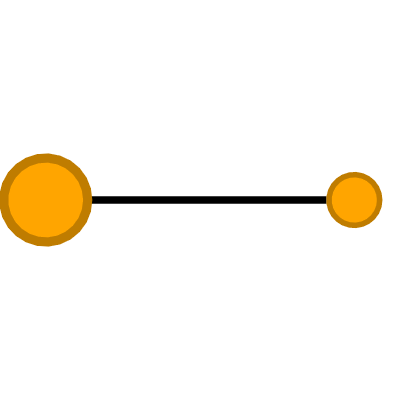 |
Sums a quantitative attribute over both ends of each tie, measuring how strongly that attribute drives tie formation. | |
| absdiff | 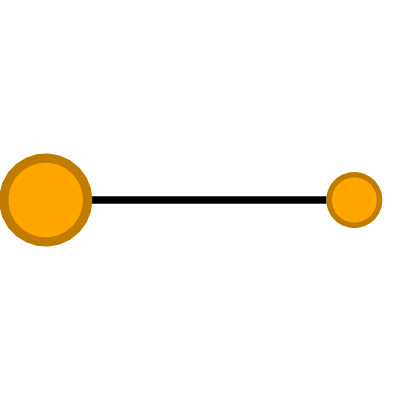 |
Sums the absolute difference in a quantitative attribute across tied nodes. Negative estimates indicate homophily, since similar nodes contribute less. | |
| edgecov | 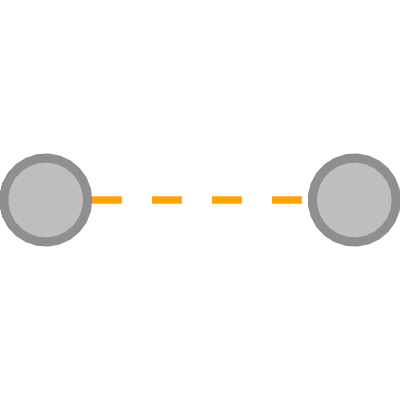 |
Sums a fixed dyad-level covariate over the observed ties, letting an external matrix such as distance or a previously observed network predict tie formation. (wasserman1996) | |
| transitiveties | 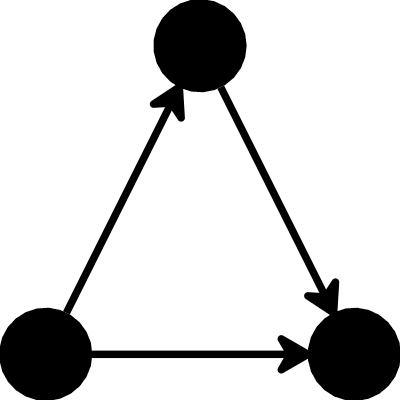 |
Counts the ties closed by at least one two-path. Unlike a triple count, a tie contributes once no matter how many shared partners it has. | |
| cyclicalties | 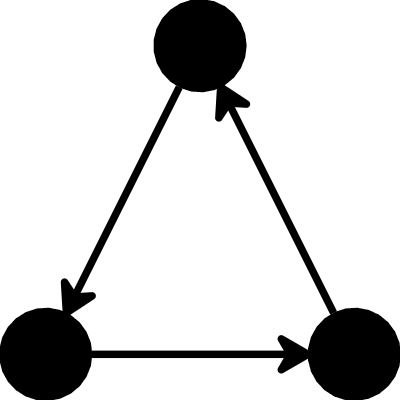 |
Counts the ties that take part in at least one cycle, capturing generalized exchange rather than hierarchy. | |
| nodeicov | 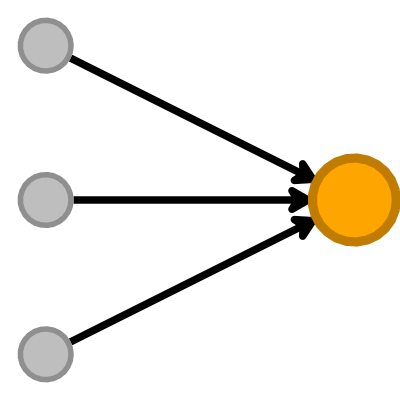 |
Sums the receiving node’s attribute value over all ties, measuring how a quantitative attribute drives incoming ties (popularity). | |
| nodeocov | 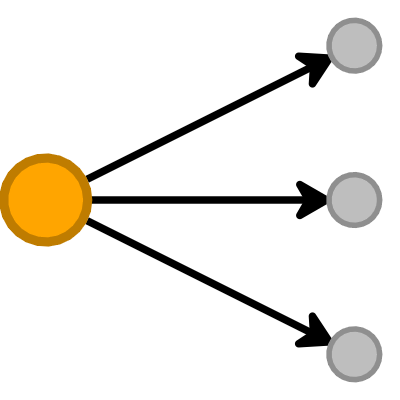 |
Sums the sending node’s attribute value over all ties, measuring how a quantitative attribute drives outgoing ties (activity). | |
| gwidegree | 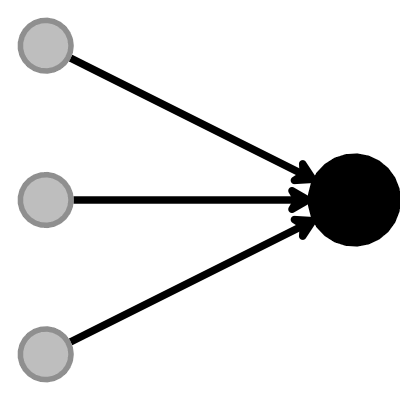 |
Summarizes the in-degree distribution with geometrically decreasing weights. Captures whether incoming ties concentrate on a few popular nodes or spread evenly across receivers. (hunter2007; robins2009) | |
| gwodegree | 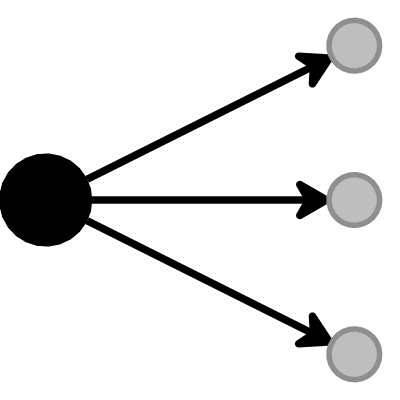 |
Summarizes the out-degree distribution with geometrically decreasing weights. Captures whether outgoing ties concentrate on a few highly active nodes or spread evenly across senders. (hunter2007; robins2009) | |
| nodeifactor | |
Counts the incoming ties received by nodes at each level of a categorical attribute, measuring how popular nodes with that value are as receivers. | |
| nodeofactor | |
Counts the outgoing ties sent by nodes at each level of a categorical attribute, measuring how active nodes with that value are as senders. | |
| kstar | 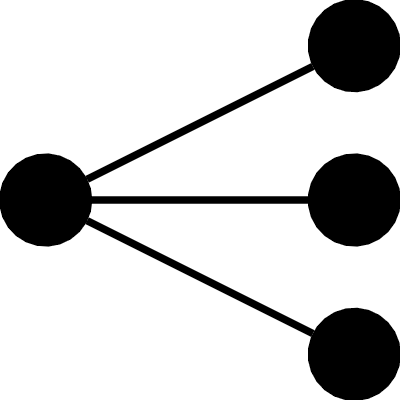 |
Counts the sets of k ties that share a common node, a Markov dependence measure of degree heterogeneity. Pass several values of k to include one statistic per star size. (frank1986) | |
| istar | 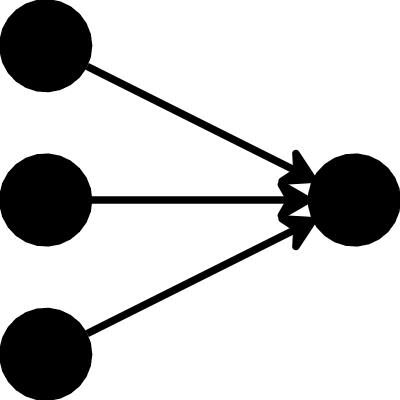 |
Counts the sets of k incoming ties that share a common receiver, capturing the spread of in-degrees (popularity). Pass several values of k to include one statistic per star size. (wasserman1996) | |
| ostar | 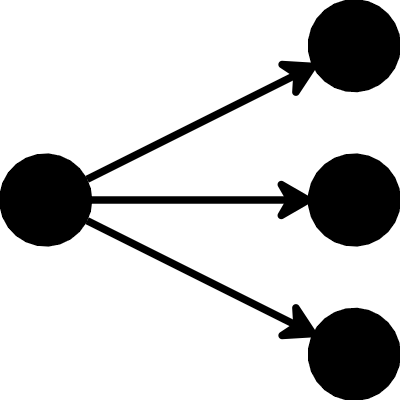 |
Counts the sets of k outgoing ties that share a common sender, capturing the spread of out-degrees (activity). Pass several values of k to include one statistic per star size. (wasserman1996) | |
| isolates | 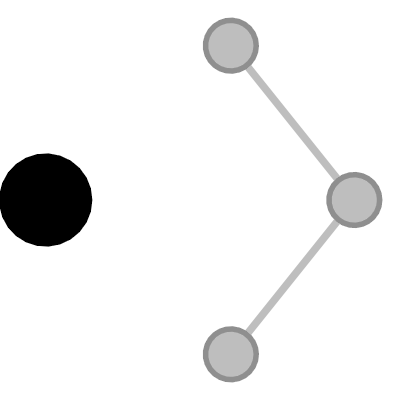 |
Counts the nodes with no ties, capturing an excess (or shortage) of isolated nodes relative to the rest of the degree distribution. | |
| degree | 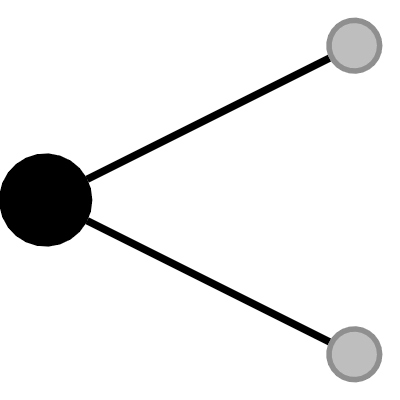 |
Counts the nodes with exactly d ties. Pass several values of d to include one statistic per degree, e.g. to model low-degree nodes explicitly. | |
| concurrent | |
Counts the nodes with two or more ties, the number of actors holding concurrent partnerships. Common in models of sexual networks and disease transmission. | |
| dgwesp | 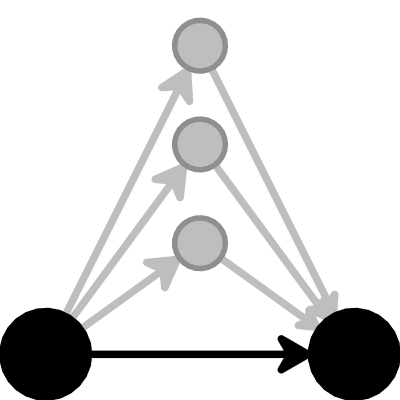 |
Directed counterpart of the edgewise shared partner statistic, measuring transitive closure with geometrically decreasing weights. Outgoing two-paths are counted by default; the term’s type argument selects a different two-path orientation. (hunter2007; robins2009) | |
| dgwdsp | 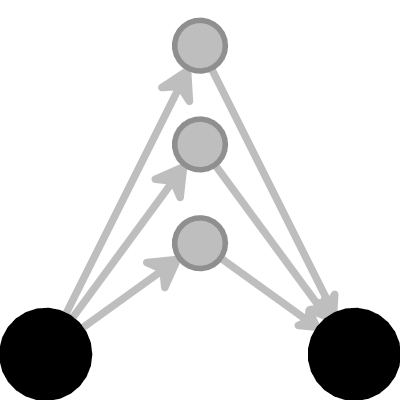 |
Directed counterpart of the dyadwise shared partner statistic, computed over every ordered dyad. Outgoing two-paths are counted by default; the term’s type argument selects a different two-path orientation. (hunter2007; robins2009) | |
| gwb1dsp | 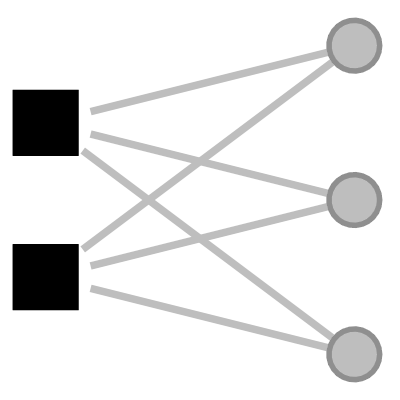 |
Summarizes how many second-mode nodes each pair of first-mode nodes has in common, weighting additional shared partners geometrically less. (wang2009; hunter2007) | |
| gwb2dsp | 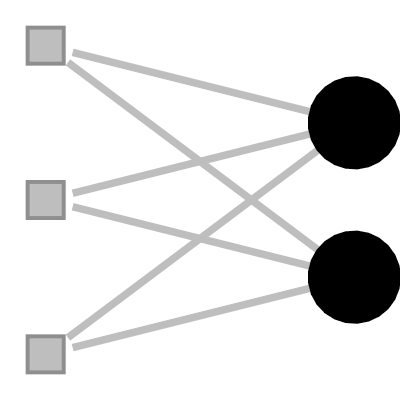 |
Summarizes how many first-mode nodes each pair of second-mode nodes has in common, weighting additional shared partners geometrically less. (wang2009; hunter2007) | |
| gwb1degree | 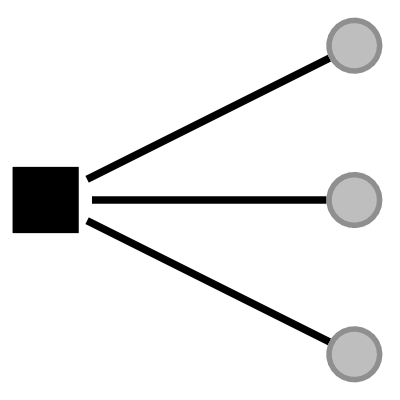 |
Summarizes the degree distribution of first-mode nodes with geometrically decreasing weights. Captures whether ties to the second mode concentrate on a few highly active first-mode nodes or spread evenly across them. (wang2009; hunter2007) | |
| gwb2degree | 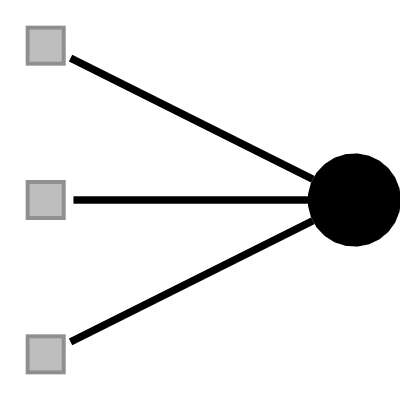 |
Summarizes the degree distribution of second-mode nodes with geometrically decreasing weights. Captures whether ties from the first mode concentrate on a few popular second-mode nodes or spread evenly across them. (wang2009; hunter2007) | |
| b1factor | 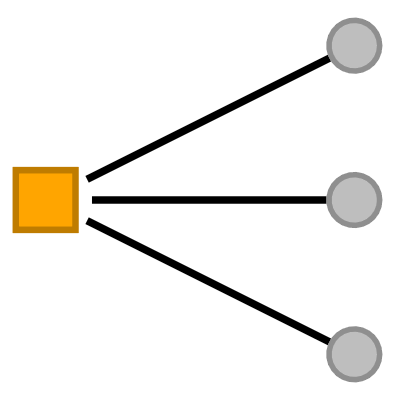 |
Counts the ties incident on first-mode nodes at each level of a categorical attribute, measuring how active those nodes are. | |
| b2factor | 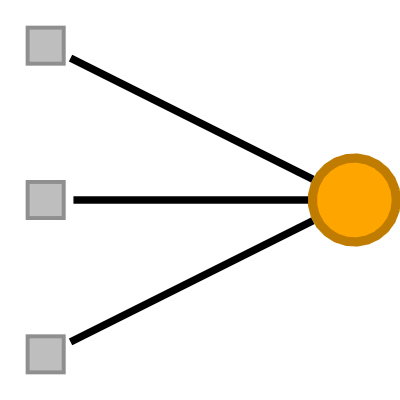 |
Counts the ties incident on second-mode nodes at each level of a categorical attribute, measuring how active those nodes are. | |
| b1nodematch | 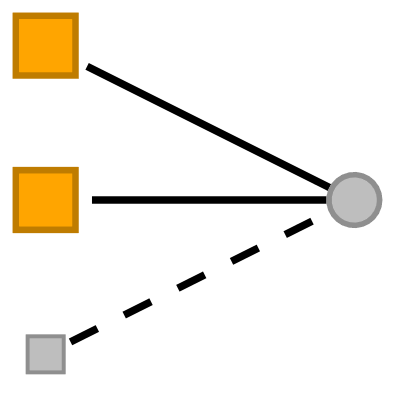 |
Counts the pairs of first-mode nodes that share an attribute value and are both tied to the same second-mode node. The alpha and beta discount parameters temper the count when nodes share many partners. (bomiriya2023) | |
| b2nodematch | 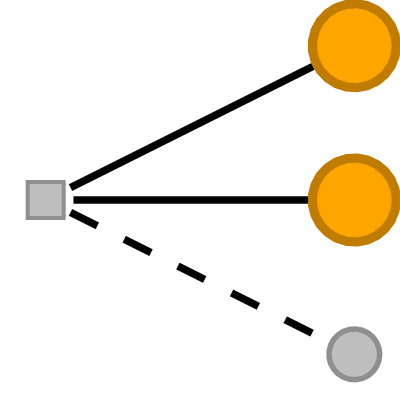 |
Counts the pairs of second-mode nodes that share an attribute value and are both tied to the same first-mode node. The alpha and beta discount parameters temper the count when nodes share many partners. (bomiriya2023) | |
| b1starmix | 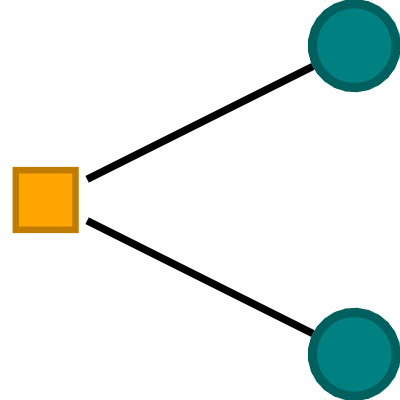 |
Counts the k-stars centered on a first-mode node with one attribute value whose second-mode neighbors all share another, capturing mixing and degree together. | |
| b2starmix | 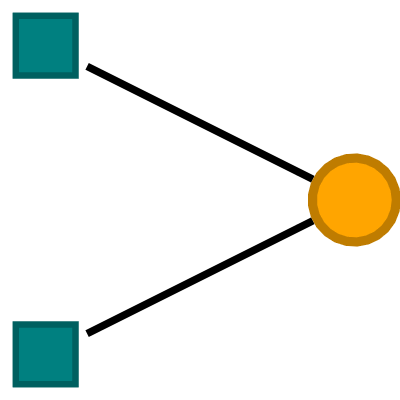 |
Counts the k-stars centered on a second-mode node with one attribute value whose first-mode neighbors all share another, capturing mixing and degree together. |
Note: Orange nodes indicate nodes with a focal attribute. Orange and teal nodes represent nodes with different values of the focal attribute. Square nodes represent nodes in the first mode and circle nodes in the second mode.
doi:10.1080/01621459.1981.10477598
doi:10.1080/01621459.1986.10478342
doi:10.1111/j.1467-9531.2006.00176.x
doi:10.1016/j.socnet.2006.08.005
doi:10.1007/BF02294547
doi:10.1146/annurev.soc.27.1.415
doi:10.1016/0025-5564(91)90014-A
doi:10.1016/j.socnet.2008.10.006
doi:10.1016/j.socnet.2008.08.002
arXiv:2312.05673
Interactive preview with tabulergm_view()
During an interactive session you can call
tabulergm_view() to open the table in the RStudio viewer
pane or the system browser:
tabulergm_view(model, include_math = TRUE, include_description = TRUE)tabulergm_view() builds a self-contained HTML page that
loads MathJax from a CDN, so LaTeX math and embedded network figures
render immediately without any additional setup.